
Data models#
A data model is a reusable, governed layer between a source system and the people who build reports. It reads one or more sources and shapes them into curated views, and those views are what report authors import when they build Excel Reports in the Excel add-in. A model lets you rename and reshape source columns into clean business fields once, so every report reads from a stable vocabulary that survives changes to the underlying source schema.
A model feeds two downstream workflows, not just reporting: Distribution Jobs (template-based output) and Contribution Campaigns (input forms). A contribution form binds to a model view the same way a report does, so curate a model as a shared vocabulary, not just a report source.
A model can read several sources at once: any number of Integrations connections and workspace files, side by side. A planning cube, a SQL database and a workbook can all feed one model, and each view draws from one of them.
Modeling a single workbook or database that lives in this workspace? You do not need a datasource connection at all. See Build a data model from a workspace file - it is the quickest way to get from a file in your workspace to a working model, with nothing added to Integrations.
Before you begin#
- At least one source to read: either a datasource connection that tests successfully (see Connect a data source), or an Excel workbook or SQLite database that already lives in this workspace (see Build a data model from a workspace file).
- You have permission to author data models in the workspace.
The model editor at a glance#
A model is edited in the workspace. The rail on the left lists the model's Source, then its joined views in a Joined views folder, then its other views in a folder per source. The Source entry's second line names the source the model reads (a connection or a workspace file), or how many when it reads several (for example 3 sources), or No source until you add one; its tooltip lists every source. Beside Source, a + Add button starts a new view (below). Select an entry to open it; your place on each screen is kept while you move between them, so you can check a table on Source and return to a half-built view without losing it.
- Source (model level). The Source screen opens on its Sources tab, which lists every source the model reads, with Change (point it at another connection or file) and Remove beside each, plus Add connection and Add workspace file… to add more (see Build a data model from a workspace file). One Direct queries checkbox on this tab applies to the whole model (see Direct queries). The Tables tab lets you look at the rows and links of any SQL source, including a SQLite or Excel workspace file, before you build a view. See Explore the source. Export on each source's row copies all its tables to one workbook (see Export a whole source to Excel). Ask AI, at the top right of the Source screen, opens the data model assistant (see Get views suggested by the AI assistant).
- A source that is missing or disabled is flagged when the model opens. If a source's connection has been deleted from Integrations or disabled, or its workspace file has been moved, renamed or deleted, an exclamation mark appears beside the source's folder in the rail (point to it to read why), and the source's row on the Sources tab explains how to fix it. This check only confirms that the connection or file is still there. It does not sign in to the source or test that it can be reached, so a problem of that kind shows when a view runs.
- Add a view. The + Add button on the rail's Source node opens a short list with one entry per source, then Joined view. Choose a source and you get a new view of that source, opened in the editor that suits it: the table designer for a SQL database, the cube view editor for Planning Analytics, and so on. Choose Joined view to combine views of the model, usually across sources (see Join views across sources).
- Views. A view is the model's unit of output: one source query plus a curated set of fields. A model can hold several, and each reads from one of its sources. Each view has four tabs, and every tab is always available:
- Design (on SQL datasources) or Connection (on every other connector) defines what the view queries, whether the view's source is a configured connection or a workspace file. On a SQL datasource you build the view on a canvas of tables and their relationships, or write it as SQL. See Build a view with the designer. On other connectors the tab holds that connector's own query settings, for example a cube data view for Planning Analytics. There is no import step on either: the view's fields follow its query, as described under the list. A joined view has a canvas of its own (see Join views across sources).
- Fields is the curated reporting field list, generated from the view's query. Each field decouples its reporting-facing Id and Name from the source column it maps to (the Mapped Field), so renaming or re-mapping a source column does not break downstream reports. Fields can be hidden, reordered, renamed, re-typed, filtered, added, or deleted.
- Variables are the
{{tokens}}that parameterize the view's query and field filters, and flow downstream to reporting and bursting. Set each one's default, whether it is required, and how a report prompts for it. See Data model variables. - Preview runs the view and shows the resolved rows after variables and field projection are applied.
Fields follow the query. There is no button to import fields. When you leave the Design or Connection tab, and when you select Save Changes, Reportworq runs any query that changed and brings the view's fields up to date. While it runs, the view reads "Updating fields from the query". If the query cannot run yet, for example because a {{variable}} has no sample value (a joined view never asks for one: its fields come from its inputs' samples or defaults), a warning explains why and the view reads "Fields may not match the query yet" until the next tab change or save. On the designer canvas, fields are added as you tick columns, so a designed view is always up to date.
Explore the source#
The Source screen has a Sources tab and, once the model has a SQL source to browse, a Tables tab. A model with nothing to browse yet opens on Sources; a connected SQL model opens on Tables. When the model has several SQL sources, the table list has one folder per source, so you always know which source a table belongs to. The table you select stays selected while you visit Sources and come back.
Use Tables to find the table a view should start from, and to check how it links to other tables before you build.
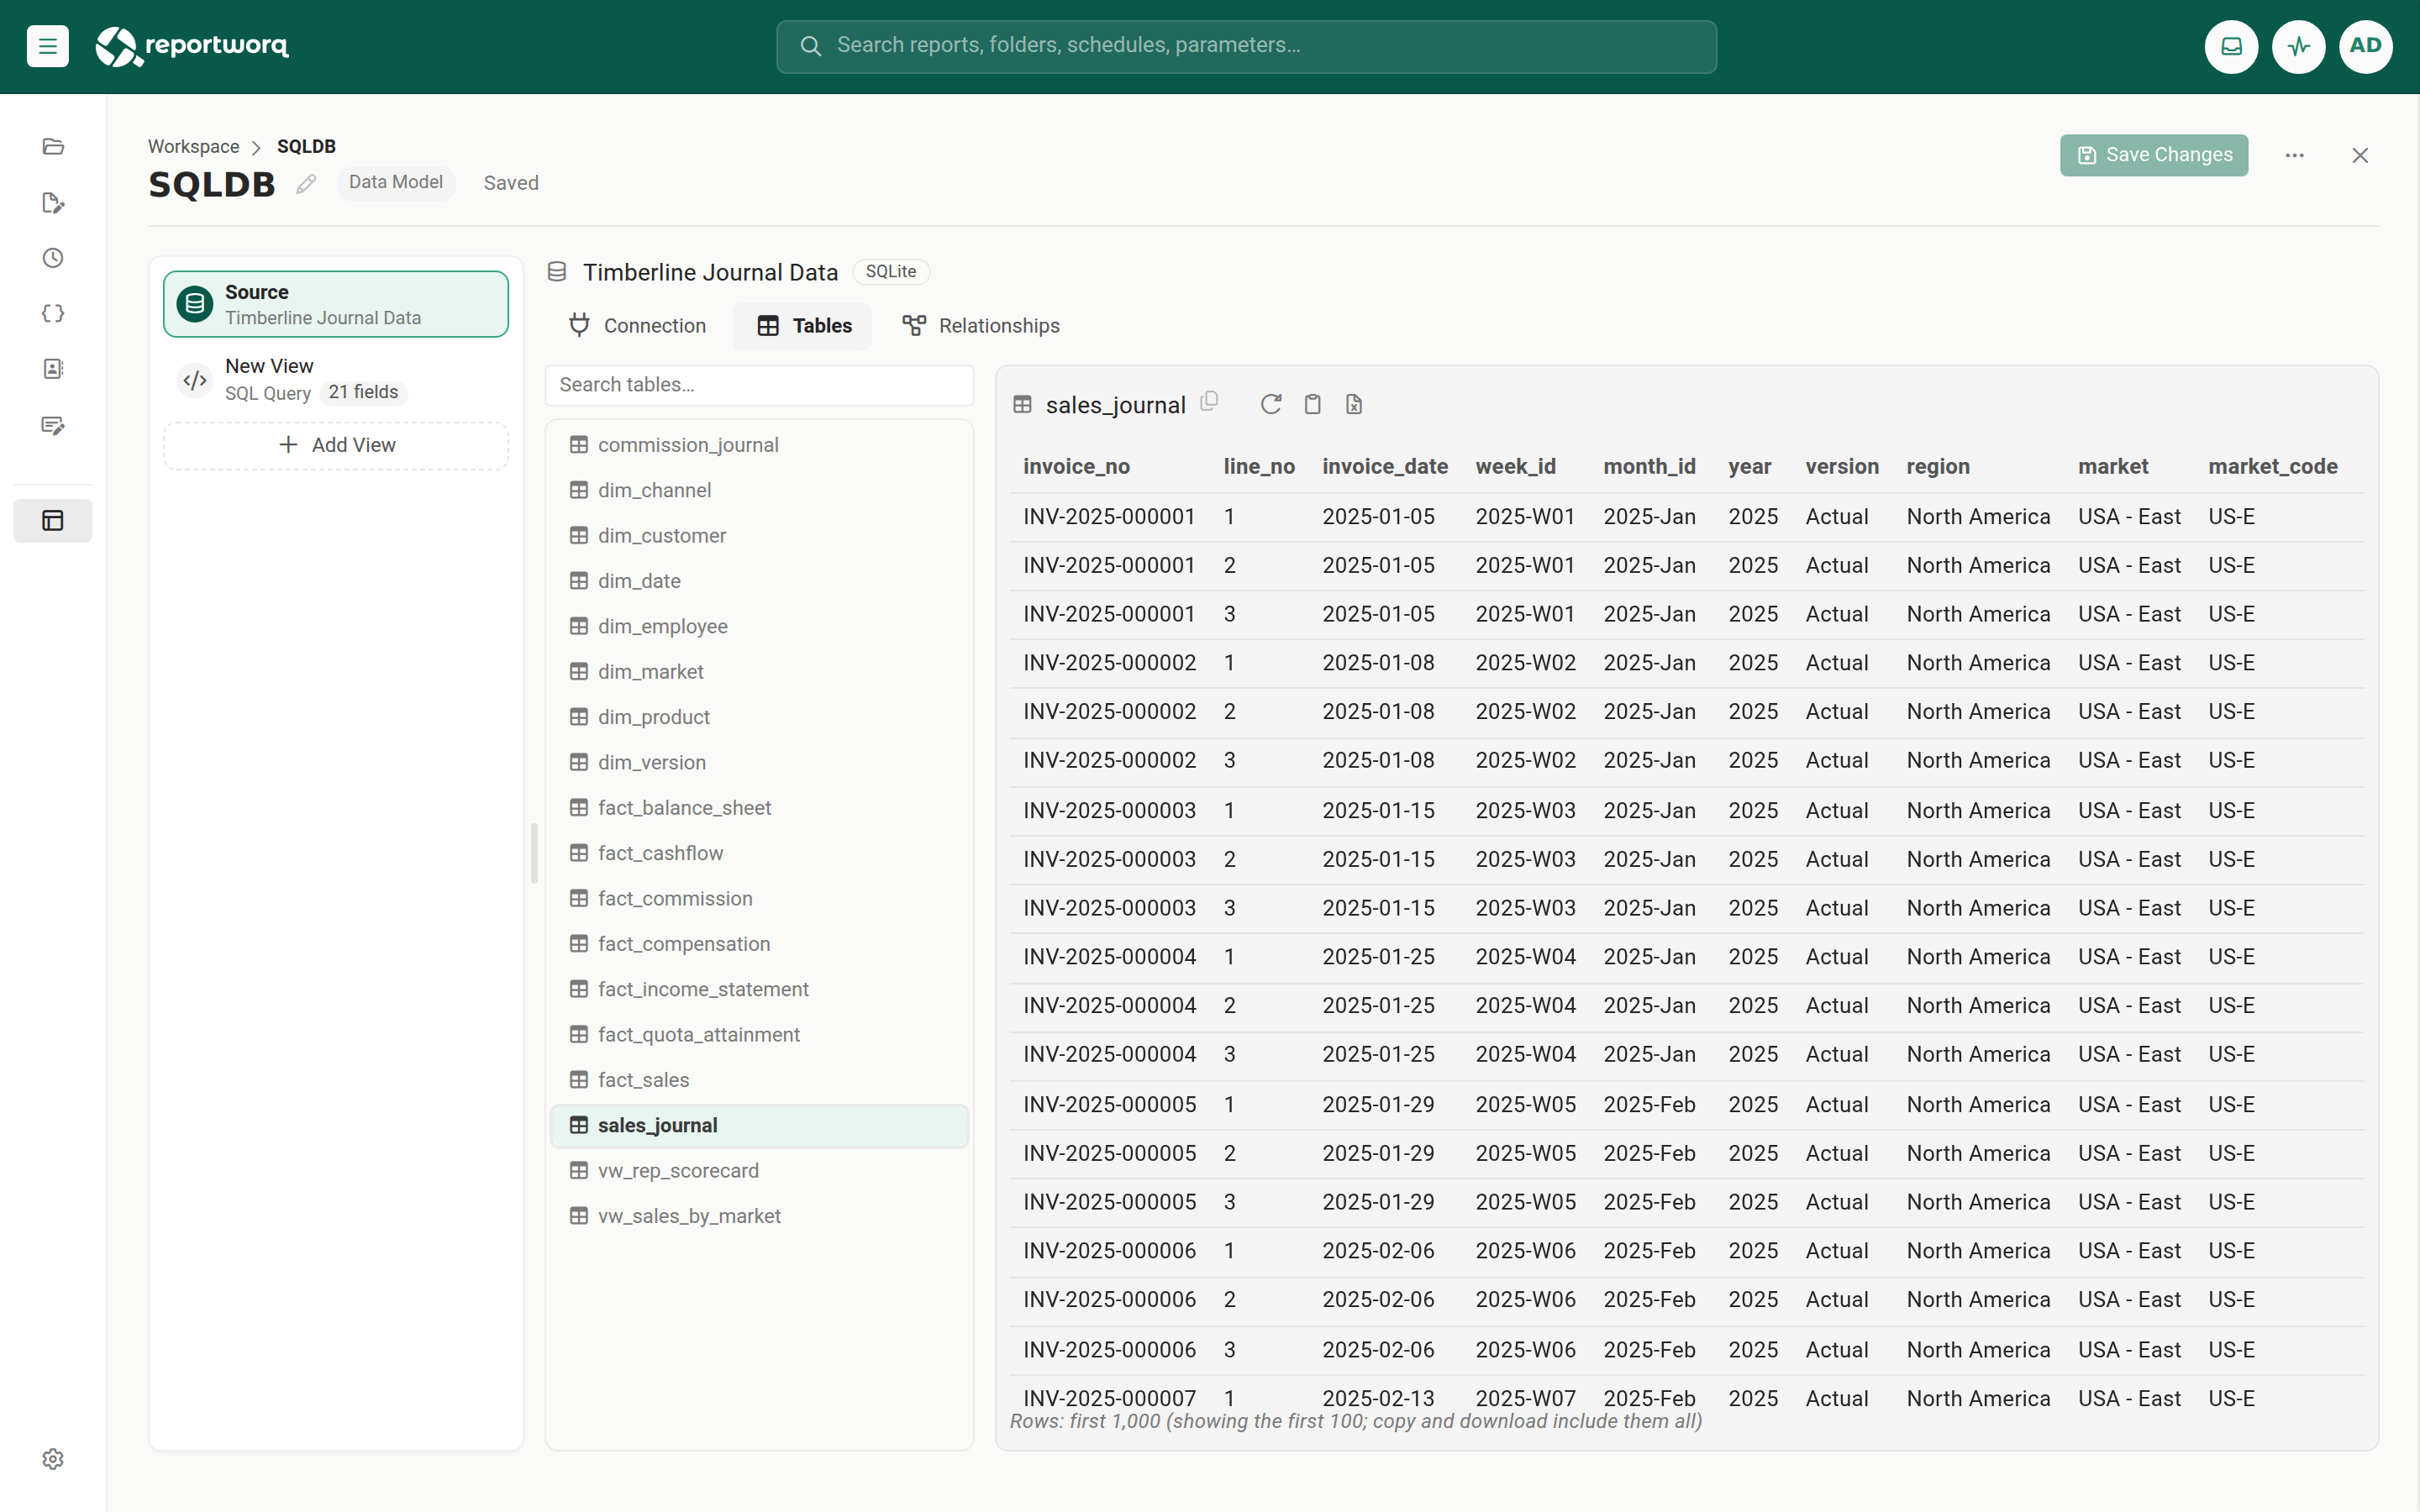
- Select Source in the rail, then Tables.
- Select a table in the list on the left. Use Search tables to narrow a long list.
- Review the table's links in the Relationships section above its rows: those the source declares, those Reportworq infers, and any you defined on the model. Select the plus sign beside Relationships to add one, or select Relationships to collapse the section and give the rows more room. See Table relationships.
- Review the table's rows. The grid reads at most 1,000 rows, and the row count under it says how many were read.
- Optional: select the clipboard button to copy every row of the table with a header row, ready to paste into Excel, or the Excel button to download a workbook of the table (what it is, its relationships, and every row). The small copy icon beside the table name copies the name. To download every table of the source at once, see Export a whole source to Excel.
The refresh button reads the table and its relationships again. Table relationships are kept per source, because a relationship becomes SQL and can only relate tables of one source. To relate views of different sources, use a joined view's relationships between views instead (see Join views across sources).
Get views suggested by the AI assistant#
The data model assistant reads the model's sources and suggests a set of views, joined views included, with business names for their fields. It is a quick way to start a model over an unfamiliar source.
The assistant needs an AI provider. An administrator adds one in Settings > Integrations (see Connect an AI provider); the assistant uses an enabled AI connection, normally the first one listed. With no provider set up, the panel says "No AI model is set up" and offers nothing to run.
What the assistant sends to your AI provider. To describe the data, the assistant sends the provider each source's name and type, its tables (up to 80 per source) with their column names and types, the links between tables, the names and fields of the model's existing views, and two sample rows from each of up to 40 tables per source (12 for a cloud connector), each value cut to 40 characters. Those sample rows are real values from your data, and they leave Reportworq for the provider. The assistant never changes the model and runs no queries of its own. Decide whether that suits the source before you select Analyze my data.
- Open the data model and select Source in the rail.
- Select Ask AI at the top right. The assistant panel opens over the editor; Save Changes stays within reach.
- Select Analyze my data. The assistant reads the sources, explains what the data is and which questions it can answer, and offers options.
- Reply in the box to steer it, for example "views for a monthly sales pack by region". When it proposes views, each comes with a check box.
- Clear the check box of any view you do not want, then select Add these views. The views are added to the rail unsaved.
- Review each view, then select Save Changes to keep them, or Discard to drop them.
Reportworq checks every proposed view against what the source really has, and leaves out (with a note) any table, column, or link that does not exist. A filter the assistant proposes becomes an optional filter variable, so a blank value returns every row. Closing the panel keeps the conversation; select Start over to begin a new one. An administrator can tune the assistant's instructions in Settings > AI Prompts (see The AI prompt store).
Join views across sources#
A joined view combines the rows of other views of the same model, usually views of different sources: actuals from the ERP beside a forecast from the planning cube, or CRM sales reps beside HR employees. Each input runs on its own, then Reportworq matches the rows by the fields you choose. You relate two views once, check the match on real rows with Test match or let Discover relationship find the key, and line up values the two systems write differently with a value mapping. Explain shows how a joined view runs and what helps or hurts it.
See Join views across sources.
Export a whole source to Excel#
Use Export to copy every table of a source into one Excel workbook, for example to hand a snapshot to someone without access, or to read a source's tables side by side. On Source, open the Sources tab and select Export on the source's row. Export appears on every source whose tables can be browsed (SQL databases, cloud connectors that expose tables, and SQLite or Excel workspace files).
Nothing is exported until you say so. The dialog looks at the source first:
- It inspects. It lists the source's tables, reads each table's columns and counts its rows. Counting rows is skipped for cloud connectors, because counting a table there would mean reading all of it; their tables show columns only.
- It gives a verdict. Quick, Medium or Large, with the number of tables, rows and cells (rows times columns) and a rough time. A table that could not be counted makes the figures a lower bound, so the verdict is never better than Medium. A very large export is refused, with a pointer to download the tables you need one at a time from the Tables tab: past 10,000,000 cells there is no Export button.
- It warns about load. Exporting reads every row of every table. On a database that reads more than 2,000,000 rows, the dialog warns that it can slow the database for other people and suggests running it outside working hours. For a cloud connector it warns that rows are read through the service's API, one table at a time, and count against its rate limits.
- You select Export. A bar shows each table's progress and one bar shows the whole export. Up to two tables are read at a time (one at a time for a cloud connector).
Stop ends the export and downloads nothing. Once every table has been read the workbook is built and sent to your browser, and there is no Stop from that point.
What the workbook contains#
| Sheet | Contents |
|---|---|
| About | The data model, the source and its connector, how many tables and rows were exported, and when. Below that, a contents list of every table with its row and column counts and any note. Each exported table's name links to its sheet. |
| Relationships | Every link between the source's tables: those the source declares, those Reportworq infers, and any you defined on the data model. |
| One sheet per table | A header row and the table's rows, with the header row frozen. Sheets follow the order of the table list. |
The file is named after the source, for example Timberline ERP.xlsx.
When a table is too big for a sheet#
A table is never refused for being large. It is cut to fit, and its row on the About sheet and in the dialog says what was cut:
- Rows. A sheet holds 1,048,575 rows of data, so a longer table keeps its first 1,048,575.
- Columns. A sheet holds 16,384 columns; the last columns beyond that are left out.
- Text length. A cell holds 32,767 characters; a longer value is cut to that length.
- Workbook size. The whole workbook is held to 10,000,000 cells. The export tracks the cells it has used as it goes, so a table that could not be counted, which may be much larger than it looks, is cut once the budget runs out, and any table after it is left out and listed as such.
A table that cannot be read, for example because of a permission, does not stop the export. It is listed on the About sheet with the reason.
Large workbooks open slowly. A Long export, in the millions of cells, can take a minute or more to build and is slow to open in Excel. For one table, download it from the Tables tab instead.
Curate the fields#
The Fields tab is where a raw source becomes a governed model. Each field shows a green mapped chip or an amber unmapped chip, recomputed automatically as you edit.
- Unmapped fields are excluded until you remap them. A field that is unmapped, whether you added it without a mapping or it lost its mapping after a source change, is left out of the model, the preview, and every report until you point it back at a source column. Unmapped does not mean "author fills it in later", there is no calculated or literal field type; unmapped simply means excluded.
- Field names must be unique within a view. A duplicate display name is rejected and the edit reverts.
- The Fields list is not paged. Field order is set by dragging rows, and a drag cannot cross a page boundary, so every field is listed on one scrolling list however many there are. Other long lists in Reportworq page at 100 rows, this one deliberately does not.
- Hidden fields stay queryable. Hiding a field removes it from the report author's field list but keeps it usable as a filter reference, so you can filter on a key column without exposing it. Use Hide all or Show all to toggle visibility in bulk.
- Rename many fields at once. The Rename menu offers Tidy names, which turns source names such as
Account_FullyQualifiedNameintoAccount Fully Qualified NameandTransaction_Type_IdintoTransaction Type ID, and Edit names as text, which lists every name one per line in field order so you can edit them in place or paste them back from a spreadsheet. Line 1 renames the first field, line 2 the second, and so on, so Apply names stays unavailable until there is exactly one non-empty, unique name per field. Both change display names only; reports bind to field ids and keep working, and Discard undoes a rename you do not want. - Filter on a variable. A field filter's value can be a
{{variable}}, so a report decides the value at run time. Reportworq writes the value into the source's query by the field's type, so it needs no quotes. To set its default and prompt, see Data model variables.
Where filters run#
A model's field filters run in the source's own query wherever the source supports it, so the database returns only matching rows and less data crosses the wire. There is nothing to switch on; large sources and selective filters are fast by default.
Sources that cannot express a filter in their own query language, such as Planning Analytics, the planning-tool APIs and other non-relational connectors, filter the rows in memory after retrieving them. You get the same result either way.
Text comparison can differ slightly. Because the database does the filtering, a text filter follows the database's own rules for comparing text (its collation), for example whether
mainematchesMaine. If a filter returns different rows than you expect, check how the source compares text.
Direct queries: modeled view or direct query#
Direct queries is a checkbox on the Sources tab, labeled "Report authors can query this data model's sources directly", and it defaults off. It applies to the whole model, not to one source. Leaving it off keeps the model view-only: authors consume the curated, published views. Turning it on lets a report author query the model's sources directly and bind to the query result's own columns, skipping the model's curated fields entirely. In the Excel add-in, the author gets one New query per source.
When to use each:
- Use a published view for governed, reusable, change-resilient reporting. The field-mapping abstraction survives source schema changes, and the view is reusable across many reports and forms.
- Use a direct query for a one-off, well-understood, or exploratory pull, for example running a known SQL extract or inspecting a source before deciding whether to invest in a curated view. Direct-query results do not carry the field-mapping abstraction, so they do not survive source changes and are not centrally reusable.
Publish a view#
Each view carries a Draft or Published state, tracked per view, so one model can hold a mix of both.
- Build and preview the view in Draft while you are still shaping it.
- Switch the view to Published when it is ready. Only published views appear in the Excel add-in's Connect picker for report authors to import.
Who sees a draft view:
- Report authors see only published views when they connect a report to the model in the Excel add-in. A draft view stays in the editor, where you can preview it, until you publish it.
When to use the two states together: publishing gates the picker, not existing bindings. A report already bound to a view keeps resolving even after you pull that view back to Draft, so you can safely revise a published view in Draft while the live reports keep running, then re-publish once the revision is validated.
Notes and limits#
- The Preview tab runs the view fresh each time, with no cache. Report display and formatting (grouping, aggregates, sort priority, format modes) are authored in the Excel add-in's list-report builder, not in the model editor.
- To work on a model, open it with Edit from its row in the workspace. Someone without edit rights can open its Properties.
Going deeper. To build a view on a SQL datasource, see Build a view with the designer and Table relationships. To combine views of different sources, see Join views across sources. For defaults, prompts, and how values are filled into a query, see Data model variables. For the field labels and query types of a specific source, see Connect IBM Planning Analytics, Connect SQL Server, OLE DB, and ODBC, and the Connector catalog. To bind a model to an Excel workbook or SQLite database in this workspace with no Integrations connection, see Build a data model from a workspace file.
Feedback on this page
Comments, questions, requests, or something missing or unclear? Email us - the page you are on is filled in for you.
Email feedback on this pageOr write to support@reportworq.com directly.